RTX 5090 cloud rental in 2026: price per hour, what fits in 32 GB, and when it beats a 4090 or an H100
Rent one RTX 5090 on Lium from $0.55 per hour on Spot or $0.65 on Secure, or a whole 8-GPU node from $0.49 per GPU-hour. 32 GB holds an 8B model in 16-bit or a 32B model in 4-bit. Prices checked 15 November 2026.
Lium team3 min read
rtx-5090
inference
pricing
buyer-guide
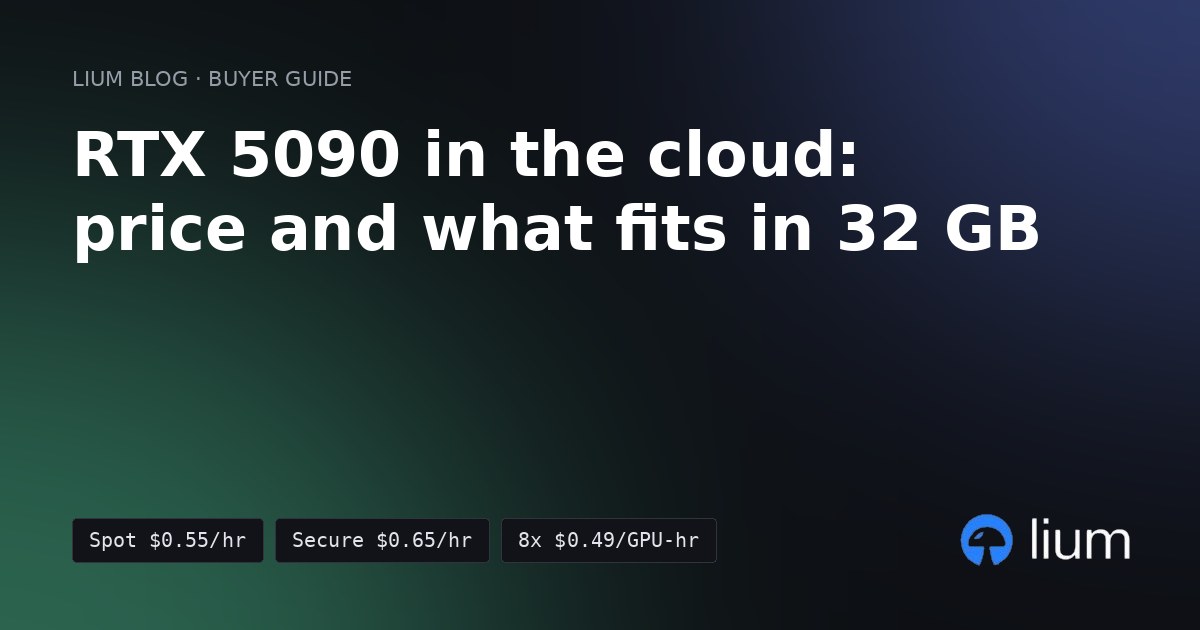
Short answer: one RTX 5090 on Lium costs from $0.55 per hour on the Spot tier and from $0.65 on the Secure tier. A whole 8-GPU node costs from $0.49 per GPU-hour, or $3.92 per hour for all eight. Rent a 5090 when your model fits in 32 GB. Rent an H100 when it needs more than 32 GB but fits in 80 GB.
(Lium prices from the public nodes feed, generated 15 November 2026 at 21:55 UTC. Lium is a marketplace where providers set the price, so check Pricing for today's numbers and Stats for how many GPUs are listed and rented.)
RTX 5090 price per hour on Lium
These are the cheapest asks for nodes you could rent at that moment. Some providers only rent a whole node, which is why the 8-GPU price per GPU is lower than the single-GPU price.
On Secure, you are credited if the provider interrupts your rental. Spot can be reclaimed, so save checkpoints and results off the pod. Lium bills per second, so a 10-minute test costs 10 minutes.
RTX 5090 specs
From NVIDIA's RTX 5090 page (read 15 November 2026):
- Memory: 32 GB GDDR7 on a 512-bit interface.
- CUDA cores: 21,760.
- Architecture: Blackwell, with 5th-generation Tensor Cores.
- Power: 575 W total graphics power.
The RTX 4090 has 24 GB GDDR6X on a 384-bit interface and 16,384 CUDA cores, from NVIDIA's page read the same day.
What fits in 32 GB
The weights take most of the memory. Each parameter is 2 bytes in 16-bit, 1 byte in 8-bit and about half a byte in 4-bit (see Hugging Face's quantization overview, read 15 November 2026). The KV cache for your context and batch comes on top.
"Tight" means the weights fit but leave little room for the KV cache, so expect short contexts and small batches.
A mixture-of-experts model still needs all its weights in memory. Seinari ran Qwen3.6-35B-A3B at 4-bit on one RTX 5090 at 1,042 decode tokens per second for a single stream. See How Seinari benchmarked on up to 16 RTX 5090s at once.
RTX 5090 vs RTX 4090 vs H100 on Lium
Same nodes feed, same read time.
- Pick a 4090 when your model fits in 24 GB with room to spare, for example an 8B model in 8-bit. It is the cheapest per hour.
- Pick a 5090 when the weights need more than 24 GB, such as a 14B model in 16-bit, or when a model that fits a 4090 needs more room for longer contexts and bigger batches. It also has more CUDA cores and a wider memory bus than the 4090.
- Pick an H100 when the model and its KV cache need more than 32 GB but fit in 80 GB, or when you need several GPUs linked by NVLink. A single H100 costs more than 3 times a single 5090 on Spot.
How to rent an RTX 5090
Install the CLI and sign in once:
bash
curl -fsSL https://lium.io/install.sh | bash
lium init
Rent one RTX 5090 for up to 2 hours:
bash
lium up --gpu RTX5090 --name my5090 --ttl 2h -yStop it when you are done:
bash
lium rm my5090 -yTo serve a model on it, follow Serve an open LLM with vLLM on a single Lium GPU. For a model-size guide across all GPUs, see Best GPU cloud for open-source LLM inference.
Prices change hourly on a marketplace. Check Pricing before you rent.
Run it on Lium
Get new posts by e-mail: Subscribe to the Lium newsletter